Friday, February 23, 2024

Linux Syscall Numbers: A Journey through Binary Analysis


Introduction:

Reverse engineering binaries is a crucial activity impacting both the realms of security and safety. When examining a program without the context syscall numbers provide, interpreting the code behavior can be daunting.

Consider this snippet of code devoid of syscall numbers:

0x0000000000000000: 48 C7 C0 01 00 00 00 mov rax, 1 0x0000000000000007: 48 C7 C7 01 00 00 00 mov rdi, 1 0x000000000000000e: 48 C7 C6 2e 00 00 00 mov rsi, 0x2e 0x0000000000000015: 48 C7 C2 0D 00 00 00 mov rdx, 0xd 0x000000000000001c: 0F 05 syscall 0x000000000000001e: 48 C7 C0 3C 00 00 00 mov rax, 0x3c 0x0000000000000025: 48 C7 C7 00 00 00 00 mov rdi, 0 0x000000000000002c: 0F 05 syscall 0x000000000000002e: 48 65 6C insb byte ptr [rdi], dx 0x0000000000000031: 6C insb byte ptr [rdi], dx 0x0000000000000032: 6F outsd dx, dword ptr [rsi] 0x0000000000000033: 20 57 6F and byte ptr [rdi + 0x6f], dl 0x0000000000000036: 72 6C jb 0xa4 0x0000000000000038: 64 21 00 and dword ptr fs:[rax], eax

Without knowledge of syscall numbers, understanding the program’s functionality, particularly its interactions with the operating system, becomes challenging. However, simply providing the context of syscall numbers can dramatically simplify comprehension. What if I tell you that the first syscall is write and the second is exit? Instantainly it became trivial to understand!

0x0000000000000000: 48 C7 C0 01 00 00 00 mov rax, 1 0x0000000000000007: 48 C7 C7 01 00 00 00 mov rdi, 1 0x000000000000000e: 48 C7 C6 2e 00 00 00 mov rsi, 0x2e 0x0000000000000015: 48 C7 C2 0D 00 00 00 mov rdx, 0xd 0x000000000000001c: 0F 05 syscall ; write(1, 0x2e, 13) 0x000000000000001e: 48 C7 C0 3C 00 00 00 mov rax, 0x3c 0x0000000000000025: 48 C7 C7 00 00 00 00 mov rdi, 0 0x000000000000002c: 0F 05 syscall ; exit(0) 0x000000000000002e: 48 65 6C insb byte ptr [rdi], dx ; H e l 0x0000000000000031: 6C insb byte ptr [rdi], dx ; l 0x0000000000000032: 6F outsd dx, dword ptr [rsi] ; o 0x0000000000000033: 20 57 6F and byte ptr [rdi + 0x6f], dl ; \b W o 0x0000000000000036: 72 6C jb 0xa4 ; r l 0x0000000000000038: 64 21 00 and dword ptr fs:[rax], eax ; d ! \0

It become easier to spot that bytes after the exit can’t be code, and that if write references them in a write to 1, stdout, they must be text!

In the snippets I just used as example spot the syscall number is trivial as mov rax, 1 for the first syscall, and mov rax, 0x3c for the second. So the example can just provide an hint of the problem. In a complex code the mov rax in question can be far away from the actual usage and in some convoluted cases, it can be moved from a register to another.

Automating the identification of syscall numbers not only aids reverse engineering for security but also can also enhance code safety. By automating this process, the amount of code that requires manual verification can be restricted. This reduction in manual effort streamlines the verification process, contributing to improved code safety and reliability.


Differences Between Architectures RISC vs CISC:

In the realm of computer architecture, the dynamic between CISC and RISC is akin to a timeless dance. CISC represents the old school, while RISC stands as the new kid on the block — although, truth be told, RISC has been strutting its stuff for at least 30 years now, which is quite a few lifetimes in architectural terms.

RISC architectures boast uniform instruction sizes, treating every instruction with equal importance. This uniformity simplifies the compiler’s task, ensuring impartial treatment of instructions. For instance, in aarch64, a 16-bit literal can effortlessly fit within a single instruction’s operating code, blending seamlessly with others within the 64k limit — a typical boundary for syscall numbers.

Conversely, CISC architectures march to a different beat. Loading an immediate value can entail performance and memory footprint costs. Even with minimal optimizations, varied instructions are often used to achieve the same outcome of loading a register with a specific value.

opcodesmnemonic
C8 1a 80 D2MOV X8, #0xd6
01 00 00 D4SVC 0
RISC: aarch64
opcodesmnemonic
93 08 e0 05li a7, 94
0f 05ecall
RISC: RiscV
opcodesmnemonic
48 c7 c0 0c 00 00 00mov rax,0x0C
73 00 00 00syscall
CISC: x86_64


opcodesmnemonic
A7 19 01 04lghi r1, 0x0104
0a 00svc 0
CISC: s390x

This architectural dichotomy sheds light on the nuances of identifying syscall numbers. RISC architectures, with their uniform instruction structure, facilitate easier identification, while CISC architectures, with their diverse and sometimes costly instructions, present a more formidable challenge.

Guess syscall numbers: How can it be done?

In the early days of computing, CPU designers anticipated the need for system call functionality directly embedded within instruction sets. For instance, the int instruction in 16-bit x86 architectures and traps in m68k systems exemplify this approach. However, as early as the 1980s, operating system developers recognized the limitations of such implementations, as the 256 functions allowed by these instructions proved insufficient. Legacy x86 systems, DOS for instance, differentiated between BIOS and operating system functions using the int number, with the OS typically consolidating its functions under a single int number, such as int 0x21. Today, the impracticality of embedding syscall numbers directly into instruction opcodes is evident, leading newer architectures like RISC-V and x86_64 to eschew this practice.

By hand: How do they do it?

Manual identification of syscall numbers is a cumbersome process, typically undertaken in two steps:
  • Locating a syscall instruction within the assembly code.
  • Tracing backward from the syscall instruction to identify registers, particularly the one containing the syscall number.
  • This meticulous process is essential for determining the specific syscall invoked by the program but highlights the need for automated tools and techniques in modern reverse engineering practices.

    Radare ESIL: How it does it?

    Radare 2 tackles the challenge of identifying syscall numbers by leveraging its ESIL framework. ESIL serves as a semantic representation of assembly instructions, enabling Radare 2 to evaluate individual instructions and emulate their behavior. Similar to LLVM-IR, ESIL provides a high-level abstraction of CPU opcode semantics, facilitating analysis and interpretation of assembly code.

    ESIL operates through a stack-based interpreter, akin to calculators, where values and operators are pushed and popped from a stack to perform operations. This post-fix notation allows for the expression of various CPU operations, including binary arithmetic, and memory operations. For example, Radare 2 can use ESIL to translate assembly instructions into understandable operations, shedding light on a program’s behavior, even for obscure architectures where traditional debugging tools may not be available. By harnessing ESIL’s capabilities, Radare 2 empowers analysts to efficiently identify syscall numbers and understand program execution flow.

    Ghidra: How it does it?

    Ghidra does not porovide an official way to solve the problem of guessing syscall numbers. Still, there’s a very well known third party script that uses Ghidra framework to provide the functionality. The Ghidra script employs symbolic propagation, a technique in reverse engineering that tracks symbolic values of program variables instead of executing the program. Specifically, the script analyzes x86 and x64 Linux binaries to resolve system calls. It identifies system call instructions, symbolically determines the values of syscall registers, and creates function definitions for each syscall. Symbolic propagation enables reasoning about register contents without actually executing the program.

    My Proposition: Static Analysis + Emulation.

    The initial concept is to emulate the code and examine the contents of registers when a syscall instruction is executed. However, a significant challenge arises: there's no assurance that the flow of code execution will necessarily reach the point of interest—the syscall.

    To address this challenge, I employ a technique I refer to as guided execution. Essentially, this method involves guiding the execution to ensure it passes over the specific instruction I need to examine.

    In the general case, this approach wouldn't provide guarantees about the accuracy of register contents. However, when it comes to syscalls, I am confident that the path I traverse to reach a syscall cannot determine the syscall number. This confidence stems from the fact that syscalls have diverse interfaces, implying that if multiple paths exist from the function start to a syscall, they will ultimately lead to the same syscall number. Subsequently, I outline the detailed procedure I employ to achieve this.

    The process commences with the user-provided function binary image, a representation of compiled machine code specific to a given function. This binary image undergoes disassembly using the libcapstone disassembler, converting the machine code into a list of assembly instructions.

    Following disassembly, an elaborate procedure ensues to generate the CFG for the function in question. The CFG serves as a graphical depiction of all feasible execution paths within the function. Each node within the graph corresponds to an instruction block, with edges denoting potential transitions between these blocks.

    An illustrative example of this intermediate step pertains to the glibc function __pthread_mutex_lock_full.

    Within this resulting CFG image, purple blocks denote instruction blocks housing syscalls, while cyan bubbles signify blocks containing a ret instruction.

    Subsequently, the task shifts to identifying a path from the function’s entry point to the instruction block housing the syscall.
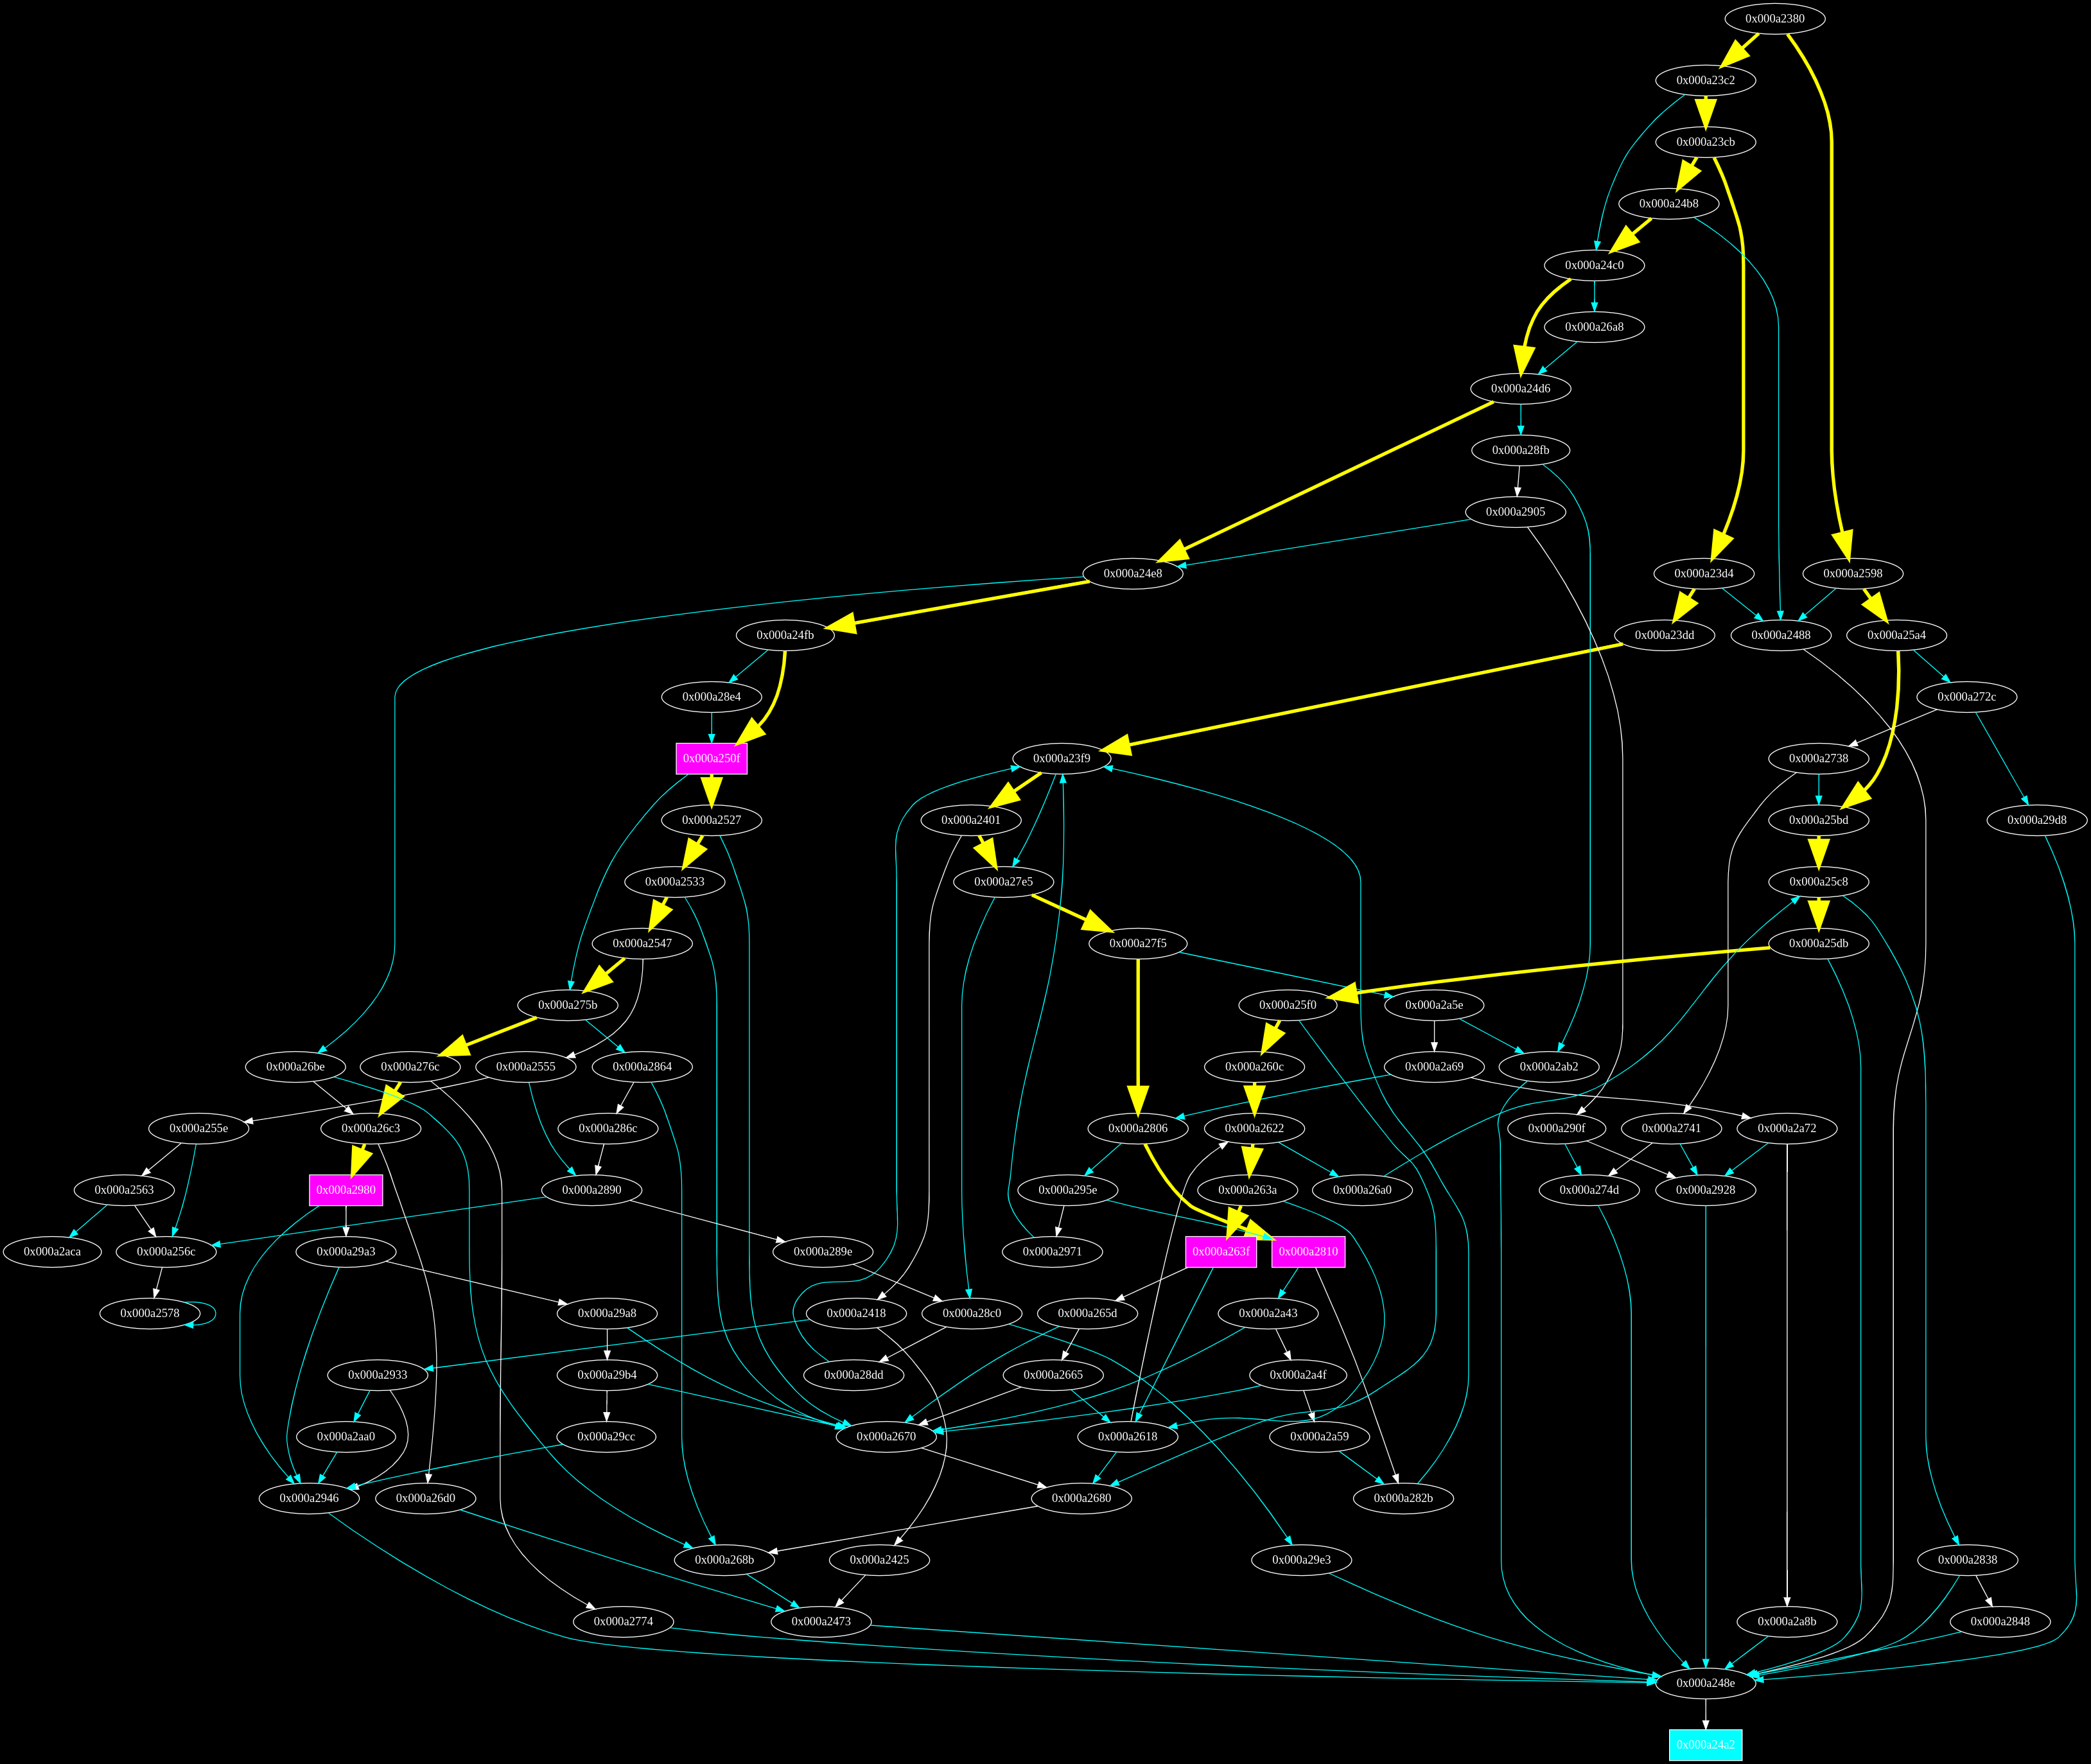
    Once the path is discerned, a further operation ensues, scanning the code to locate any call instructions along the path. These call instructions are then substituted with nop instructions, ensuring guided execution remains focused solely on the path leading to the syscall instruction block and doesn’t veer off due to calls to other functions absent from the binary image.

    With call instructions replaced, guided execution is executed using libunicorn. During this process, each instruction block along the path is executed sequentially, with the context (CPU state) of each block utilized to initiate execution of the subsequent block.

    Upon reaching the syscall instruction, register values are inspected to ascertain the syscall number.


    Addressing concerns and outlining why it’s effective in this use case.

    The PoC

    To apply this concept in a practical context, I aimed to create a Proof of Concept (PoC), opting to develop it as a Radare2 plugin. Below, I present the implementation for both versions of Radare:

  • Radare2.
  • Rizin.
  • Patching the Code

    As I delve into the intricacies of Linux binaries, the necessity of patching becomes evident in my quest to uncover the elusive syscall numbers. Patching serves as a crucial tool to remove distractions and ensure a clear path to my destination.

    However, the task of patching is notably more complex in CISC architectures compared to RISC. In CISC, such as x86, branch instructions vary in length, adding layers of intricacy to the process. This complexity is compounded by the need to decipher the true meaning behind seemingly innocuous instructions like the nop instruction.

    In the realm of x86 architecture, the nop instruction is a facade for the xchg (e)ax, (e)ax instruction. This revelation sheds light on the true nature of nop, enabling me to craft multibyte instructions that effectively clear my path of obstructions.

    To achieve this, I employ the Gauss formula, a stroke of genius that allows me to create a function capable of generating multibyte nop instructions of any desired size. Armed with this solution, I navigate the intricate landscape of x86 architecture with newfound confidence, inching closer to my ultimate goal with each patch applied.

    const char multibyte_nop_x86[]= "\x90" "\x66\x90" "\x0f\x1f\x00" "\x0f\x1f\x40\x00" "\x66\x66\x66\x66\x90" "\x66\x0f\x1f\x44\x00\x00" "\x0f\x1f\x80\x00\x00\x00\x00" "\x0f\x1f\x84\x00\x00\x00\x00\x00" "\x66\x0f\x1f\x84\x00\x00\x00\x00\x00"; const char multibyte_ret_nop_x86[]= "\xc3" "\xc3\x90" "\xc3\x66\x90" "\xc3\x0f\x1f\x00" "\xc3\x0f\x1f\x40\x00" "\xc3\x66\x66\x66\x66\x90" "\xc3\x66\x0f\x1f\x44\x00\x00" "\xc3\x0f\x1f\x80\x00\x00\x00\x00" "\xc3\x0f\x1f\x84\x00\x00\x00\x00\x00"; #define MBNOP(n,t) (t==NOP_ONLY?multibyte_nop_x86 + (((n-1) * n)/2):multibyte_ret_nop_x86 + (((n-1) * n)/2))

    No Return Functions.

    The primary method employed by this plugin is emulation, where it does not have access to a context, meaning that function arguments are undetermined. Instead of emulating the entire function, it selectively executes the sequence of blocks of code leading from the function’s entry point to the point where a syscall is invoked, which is the guided execution I presented earlier.

    To achieve this, the plugin performs an analysis of the target function and creates a CFG. The CFG serves as a navigational tool to identify the path of blocks leading to the block that contains the syscall.

    In this context, “blocks,” or instruction blocks, are defined as sequences of instructions without any branching, typically terminating at a branch instruction. CALL instructions are typically treated as NOP instructions and are patched out of the binary.

    However, a unique challenge arises when dealing with the glibc library, specifically, when encountering the __libc_fatal function. Unlike other functions, this troublemaker does not conform to the assumed behavior of returning, rendering the standard treatment of call instructions inappropriate.

    I’ve decided a special treatment for this __libc_fatal function implementing ad hoc solution that transforms it into a RET instruction, allowing the plugin to function effectively in such cases.

    Jump Tables: Tackling complexities introduced by jump tables.

    The current plugin implementation effectively follows the CFG of a given function, providing accurate results in most scenarios. However, there’s an edge case that the current algorithm cannot handle correctly. This occurs when a switch case is implemented using a jump table. The current approach handles jmp instructions by considering no forward path, relying solely on the branch path. However, in cases involving jump tables, the branch path can be multiple and located far away from the code under examination.

    A temporary solution focusing specifically on the syscall number can be summarized as follows:

  • Collection of Syscall Numbers: During the examination of the function’s code, the plugin should collect information about syscall numbers and their corresponding positions within the code.
  • Handling Non-Reached CFG Blocks: If the CFG analysis encounters non-reached blocks containing a syscall, the plugin could execute them to determine if the syscall number can be deduced.
  • Epilogue:

    This endeavor stands as a PoC for a concept, while this blog post acts as a platform for others to voice their thoughts on this notion. I find it quite promising, although it requires refinement on multiple fronts. Summarizing key insights and takeaways. Encouragement for further exploration and research in the realm of binary analysis.

    Monday, January 29, 2024

    Navigating the Labyrinth: Battling Duplicate Symbols in the Kernel

    Introduction

    Hey folks! Ever wondered what it’s like to venture into the wild world of kernel development? Well, let me tell you, it’s not a walk in the park. In this post, I want to tell you about when I stumbled upon a head-scratcher – the conundrum of duplicate symbols in the Linux kernel.

    Why Duplicate Symbols Exist in the Kernel and How is it Possible?

    Kernel development is a complex and intricate process that involves the compilation and linking of numerous C source files to create the final executable. The kernel comprises multiple C files, each translated into an object file during compilation. The linking process that follows, is where these object files are brought together for form intermediate objects (or modules) and at last the kernel binary image. The linker relies on symbols, identifiers that represent variables or functions, to establish connections between different parts of the code. Importantly, these symbols the linker needs to use, must be unique within a linking session to ensure the process success.

    In any given object file, there are two types of symbols: exported and non-exported. Exported symbols, designated to be used externally, must be unique within the set of objects the needs to be linked together to ensure the linking process success. On the other hand, non-exported symbols, often associated with functions declared as static, are not subject to the same uniqueness constraints, and the object linked together may end up in containing non exported symbols names that are not unique within the set.

    As said, exported symbols must be unique to permit the linker’s job, but no strict rules are imposed on non-exported symbols. This characteristic is not something that must exist in general, but it is inevitably true in the vast codebase of the Linux kernel, where this occurrence is not uncommon.

    Adding complexity to this scenario is the use of header files. Some symbols, particularly small inline functions, find their definition in these header files. While this is a common practice, it introduces the possibility of duplicate symbols, and when this happens, it is not just the result of chance, it is something structural that produces duplicates scientifically, since header files can be included in different compilation units, therefore the same function may appear multiple times within the kernel executable.

    A notable contributor to the presence of duplicated symbols lies in the compatibility binary format ELF, where a hack in the compat_binfmt_elf.c file introduces duplicate symbols as a consequence of c file inclusion.

    In essence, the kernel’s symbols are not granted to be unique in any way, and in fact there are duplicated symbols in the kernel.

    ~ # cat /proc/kallsyms | grep " name_show" ffffcaa2bb4f01c8 t name_show ffffcaa2bb9c1a30 t name_show ffffcaa2bbac4754 t name_show ffffcaa2bbba4900 t name_show ffffcaa2bbec4038 t name_show ffffcaa2bbecc920 t name_show ffffcaa2bbed3840 t name_show ffffcaa2bbef7210 t name_show ffffcaa2bbf03328 t name_show ffffcaa2bbff6f3c t name_show ffffcaa2bbff8d78 t name_show ffffcaa2bbfff7a4 t name_show ffffcaa2bc001f60 t name_show ffffcaa2bc009890 t name_show ffffcaa2bc01212c t name_show ffffcaa2bc025e2c t name_show ffffcaa2a052102c t name_show [hello] ffffcaa2a051955c t name_show [rpmsg_char]

    Ok, there are duplicate symbols, but does this really matters?

    It is a fair question, and I can anticipate that you can live a long life full of joy without even knowing about this problem. You can be even a kernel developer at some level and ignore the thing. Some kernel maintenance people cannot ignore the issue, though, since it won’t spare them from the pain of facing it. Whoever has done kernel tracing at some level is not spared by stomping on it, and also the few people who did live patching had to deal with this at a harder level. To understand how kernel duplicated symbol names can impact anyone, we must start from the fundamentals of the tracing system, the kernel symbol table aka kallsyms. The kallsyms is a giant table where any kernel symbol is noted together with its address. This table allows the tracing subsystem to locate a function within the kernel address space with a simple lookup. All this works particularly well; from a name, you have an address, as long as you have unique symbols.

    Tracing a duplicate symbol, on the other hand, is a pain since you cannot know if the address kallsyms provides is the one you intended to watch. Saying that you can try again in the tracing usecase, things become more serious if you need to patch it.

    Consider the scenario of tracing a specific function for debugging or performance analysis. With duplicate symbols, the tracer picks the one of the matching symbols (typically the first), but nobody knows if it is tho one you intended, leading to inaccurate results and potentially misinforming the trace engineer. The challenge amplifies when it comes to live patching, a process that involves modifying the kernel code at runtime. In such a delicate operation, precision is paramount, and the presence of duplicate symbols introduces an element of uncertainty. Need to say that the livepatch subsystem has somehow solved the problem of the uncertainty by using kallsyms_on_each_match_symbol, but it is still a suboptimal solution.

    In essence, the existence of duplicate symbols adds an extra layer of complexity for those involved in kernel tracing and live patching.

    Does this Really Happen, or is it Just a Potential Problem?

    Well, the first time I stumbled upon this issue was when I began developing a tool to generate diagrams illustrating the dependencies between functions within the Linux kernel. Enter ks-nav, a tool designed to create graphs for any Linux kernel function, showcasing potential relations between various kernel subsystems. The software analyzes the kernel, exporting information into a database used to produce insightful diagrams. During this endeavor, I encountered the duplicate symbols issue for the first time. For my use case, I simply needed to address the duplicated names by renaming them adding leading sequence numbers, a seemingly manageable task at the time.

    However, my subsequent encounter with duplicate symbols proved to be more challenging, and I instinctively steered away from confronting it directly. I was assigned the task of investigating a bug in a system that experienced a complete freeze and became unusable when utilizing ftrace functions. Without delving into the intricate details of the bug, the crux of the matter was that a peripheral generated an excessive number of interrupts, overwhelming the system to the point where the ftrace overhead left no CPU time for other operations.

    Having identified the root cause, my intention was to create a demonstrator that would vividly illustrate the source of the problem. I aimed to hard-code a filter into the interrupt controller code to exclude the troublesome interrupt from being serviced. My strategy involved live-patching a function into the interrupt controller code, replacing it with the same function but with the filter hard-coded. It was a nice strategy, except that live patch does not support aarch64, and the interrupt controller symbol I wanted to replace, existed in thr two interrupt controller drivers built in the target kernel: the GIC and the GICv3.

    Here are the links to the relevant kernel source files:

    I managed to find a workaround for the issue, albeit in a somewhat hacky manner. However, this experience prompted me to recognize the need for a more generalized solution to address the challenges posed by duplicate symbols in the kernel.

    In Any Case, What Havoc Do These Duplicate Symbols Wreak?

    Let’s assume that the kernel itself doesn’t exhibit any substantial behavioral defects, and this issue predominantly affects the tracing system. Having a name that potentially does not precisely identify a function raises three significant issues with the current implementation. Let’s delve into the details:

    1. Uncertainty in Symbol Address: The function responsible for looking up a name in the Linux kernel is kallsyms_lookup_name. It returns the address of the first symbol it encounters with that name. This introduces a problem because, given a symbol name, you can’t be certain that the address you receive corresponds to the specific function you’re interested in.
    2. Identification Challenge: With multiple matching symbols, it’s not straightforward to determine which one is the intended symbol with a given name. The lack of a clear distinction complicates the selection process.
    3. Difficulty in Addressing Specific Symbols: Assuming you’re aware that the first matching symbol with a given name is not the one you seek, it becomes challenging to address any other symbol. The process of singling out the correct symbol becomes nontrivial.

    To address these challenges, the kernel provides kallsyms_lookup_names, which returns all symbols with the same name. While this can help refine the search, it doesn’t entirely resolve the issue. The live patch subsystem uses kallsyms_lookup_names in conjunction with kallsyms_on_each_match_symbol to apply a function on each entry and select the appropriate one. However, this approach has limitations, and its application is primarily confined to the live patch subsystem. If the function to apply as a filter were a BPF, it would be relatively more manageable.

    The underlying problem is that, even with these mechanisms, kernel developers can only select the desired symbol in a convoluted way. From a user-space perspective, a trace engineer is left with addresses that are not particularly user-friendly. Moreover, determining the nature of a symbol is solely reliant on the address context, requiring the trace engineer to make educated guesses based on the available information. This complexity adds an extra layer of difficulty for those working with kernel tracing, underscoring the impact of duplicate symbols on practical kernel development scenarios.

    So, is there any solution to fix this?

    Before delving into solutions, it’s essential to acknowledge additional requirements that any potential resolution should meet:

    1. Preserve the current state to not impact the ecosystem: Any solution addressing duplicated symbols in the kernel should strive to maintain the current state, ensuring minimal disruption to the ecosystem or any existing solutions implemented by trace software.

    Now, let’s explore the possible solutions. A straightforward approach involves renaming all duplicate symbols to make each symbol unique. However, this is no trivial task, given the significant changes required. Moreover, there’s currently no preventive mechanism in place to avoid the recurrence of this issue. Any attempt to pursue this path should include a strategy to prevent the kernel from encountering the same situation in the future. It’s worth noting that renaming several symbols simultaneously could have unforeseeable impacts on the ecosystem.

    So, what other options are available to address this issue? As of my investigation in July 2023, there were only two attempts to tackle the “Identification Challenge.”

    My proposal to address this problem involves adding aliases to duplicate symbols.

    Adding Aliases to Duplicate Symbols, can be really solve the problem?

    My approach to resolving this problem is to introduce aliases for duplicate symbols. I believe it can provide a valuable solution for the problem, and here’s how aliases can address the identified issues:

    1. Uncertainty in Symbol Address: Aliases need to be unique. Tracing a unique alias allows users to ensure that the provided address corresponds to the desired function.
    2. Identification Challenge: The alias embodies information useful for correctly understanding the symbol’s nature or source.
    3. Difficulty in Addressing Specific Symbols: The uniqueness of the alias allows the symbol to be selected simply by using the alias.
    4. Preserve the Current State to Not Impact the Ecosystem: By adding aliases without removing the previous symbols, any ecosystem software that dealt with the problem in its way is preserved. This approach allows for a gradual migration to using aliases.

    Indeed, special attention must be given to how aliases are generated. After consulting with the community, I opted to use a string as the alias, comprising the file path and the line number where the symbol is defined. This ensures the alias is not only unique but also carries crucial information for identifying the symbol.

    Is yours proposal something concrete, or is it just words in the air?

    This proposal is tangible and has undergone several iterations, currently standing at its 7th version as of January 2024. Detailed implementation discussions are more suited for the mailing list or the GitHub repository, where the development is actively taking place.

    In its current state, the patch can:

    • Automatically detect symbols requiring aliases during the kernel build.
    • Add aliases to the core kernel image.
    • Add aliases to modules.
    • Export a file with symbol name statistics.
    • Add aliases to out-of-tree kernel modules using symbol statistics.

    This is how the symbols should look with the patch applied:

    ~ # cat /proc/kallsyms | grep " name_show" ffffcaa2bb4f01c8 t name_show ffffcaa2bb4f01c8 t name_show@kernel_irq_irqdesc_c_264 ffffcaa2bb9c1a30 t name_show ffffcaa2bb9c1a30 t name_show@drivers_pnp_card_c_186 ffffcaa2bbac4754 t name_show ffffcaa2bbac4754 t name_show@drivers_regulator_core_c_678 ffffcaa2bbba4900 t name_show ffffcaa2bbba4900 t name_show@drivers_base_power_wakeup_stats_c_93 ffffcaa2bbec4038 t name_show ffffcaa2bbec4038 t name_show@drivers_rtc_sysfs_c_26 ffffcaa2bbecc920 t name_show ffffcaa2bbecc920 t name_show@drivers_i2c_i2c_core_base_c_660 ffffcaa2bbed3840 t name_show ffffcaa2bbed3840 t name_show@drivers_i2c_i2c_dev_c_100 ffffcaa2bbef7210 t name_show ffffcaa2bbef7210 t name_show@drivers_pps_sysfs_c_66 ffffcaa2bbf03328 t name_show ffffcaa2bbf03328 t name_show@drivers_hwmon_hwmon_c_72 ffffcaa2bbff6f3c t name_show ffffcaa2bbff6f3c t name_show@drivers_remoteproc_remoteproc_sysfs_c_215 ffffcaa2bbff8d78 t name_show ffffcaa2bbff8d78 t name_show@drivers_rpmsg_rpmsg_core_c_455 ffffcaa2bbfff7a4 t name_show ffffcaa2bbfff7a4 t name_show@drivers_devfreq_devfreq_c_1395 ffffcaa2bc001f60 t name_show ffffcaa2bc001f60 t name_show@drivers_extcon_extcon_c_389 ffffcaa2bc009890 t name_show ffffcaa2bc009890 t name_show@drivers_iio_industrialio_core_c_1396 ffffcaa2bc01212c t name_show ffffcaa2bc01212c t name_show@drivers_iio_industrialio_trigger_c_51 ffffcaa2bc025e2c t name_show ffffcaa2bc025e2c t name_show@drivers_fpga_fpga_mgr_c_618 ffffcaa2a052102c t name_show [hello] ffffcaa2a052102c t name_show@hello_hello_c_8 [hello] ffffcaa2a051955c t name_show [rpmsg_char] ffffcaa2a051955c t name_show@drivers_rpmsg_rpmsg_char_c_365 [rpmsg_char]

    However, refinement and alignment with community standards are still ongoing, requiring further iterations. The ultimate acceptance of this work into the kernel remains uncertain, but this article serves as a testament to the effort invested.

    Friday, January 5, 2024

    Unveiling CPU Count in a System: A Dive into Linux Utilities and Functions


    Introduction:

    Understanding the computational capabilities of a system can be pivotal in optimizing software performance. The quest to determine the number of CPUs within a system often leads to exploration and evaluation of various methods. This pursuit becomes particularly critical when developing low-level tools for Linux, where having an accurate insight into the available CPU count is essential for efficient resource utilization and task allocation. In this article, I delve into different approaches to uncovering this crucial system attribute, aiming to provide insights for developers grappling with similar challenges.

    Initial Proposition:

    In my pursuit of determining the number of CPUs within a Linux system, my initial approach mirrored what I typically did from the command line: cat /proc/cpuinfo. It’s worth noting that while the command line utility nproc caters to the same query, my familiarity with the proc method predates my acquaintance with nproc. Hence, it was my instinctive choice for the initial implementation of a function to retrieve this vital information programmatically.

    int nproc() {
            int cpu_count = 0;
            char line[100];
            FILE *file;
    
            file = fopen("/proc/cpuinfo", "r");
            if (file == NULL) {
                    perror("Error opening file");
                    exit(EXIT_FAILURE);
            }
    
            while (fgets(line, sizeof(line), file)) {
                    if (strncmp(line, "processor", 9) == 0) {
                            cpu_count++;
                    }
            }
    
            fclose(file);
            return cpu_count;
    }

    Does this implementation work? Yes, it does provide the expected CPU count. However, despite its functionality, I find myself dissatisfied with this method for several reasons, which I’ll delve into shortly.

    Concerns on the Solution:

    While the initial /proc/cpuinfo approach effectively retrieves CPU information, several concerns arise, prompting dissatisfaction with this simplistic method:

    1. Oversimplicity: The code’s apparent simplicity, merely opening a file and parsing statements, raises skepticism. Its straightforward nature seems inadequate for a task as critical as determining CPU count within a system. This simplicity might overlook nuances or potential intricacies within different system environments.
    2. Uncertainty in /proc/cpuinfo Stability: /proc/cpuinfo provides information designed for human readability. This readability doesn’t guarantee immutable structure or content, leaving room for future modifications by kernel developers. While changes aren’t imminent, relying solely on this file may pose a risk of unexpected alterations in its format or content, impacting the function’s reliability.
    3. Dependency on Procfs: The reliance on procfs introduces a constraint, assuming its presence and accessibility, which isn’t universally guaranteed. In specific embedded Linux systems or constrained environments, procfs might not be mounted or accessible. Assumptions like these could jeopardize the function’s portability and reliability across diverse Linux distributions and setups.
    4. Preference for Syscall Stability: A preference emerges for utilizing syscalls, known for their stability and less prone to alterations compared to file-based interfaces like procfs. Syscalls, by design, tend to remain more consistent across Linux distributions and versions, offering a more robust foundation for critical functionalities like retrieving CPU count.

    The sysconf() Function:

    Is there a standardized, reliable way to retrieve CPU count programmatically? After a comprehensive search, one function stood out as a prevailing best practice: sysconf(_SC_NPROCESSORS_CONF). This function, available in the POSIX standard, offers a promising solution for obtaining the number of processors in a system.

    What is sysconf()?

    At its core, sysconf() is a system call that allows access to configurable system variables. Specifically, _SC_NPROCESSORS_CONF is a parameter used to query the number of processors configured in the system. Additionally, _SC_NPROCESSORS_ONLN exists, reporting the number of CPUs effectively active.

    Does it provide a solution for this?

    Indeed, sysconf(_SC_NPROCESSORS_CONF) serves as a robust and standardized means to obtain CPU count programmatically. Its utilization ensures compatibility across various Linux distributions and versions, contributing to code portability.

    How sysconf() is implemented in the guts of libcs:

    glibc implementation:

    Navigating through the labyrinthine structure of glibc, a colossal library accommodating various systems, one discovers numerous implementations catering to different operating environments. Amidst this complexity, glibc’s handling of sysconf() for Linux systems proves enlightening.

    In scrutinizing glibc’s codebase, particularly for Linux-specific implementations, it’s evident that glibc relies on sysfs as its primary source for retrieving CPU count information. The main method employed by glibc to provide this data involves accessing /sys/devices/system/cpu/possible. This file seemingly contains the requisite CPU count information, hence serving as the cornerstone for glibc’s approach.

    However, acknowledging the potential unpredictability of specialized file system resources, glibc developers have implemented a fallback system in case the primary method fails. The fallback function, get_nprocs_fallback(), comprises alternative methods to retrieve CPU count information:

    1. get_nproc_stat(): This method mirrors my initial implementation; it parses /proc/cpuinfo and tallies occurrences of cpu, akin to counting processors. While functional, it remains subject to the same concerns surrounding /proc/cpuinfo stability and dependencies on procfs availability.

    2. __get_nprocs_sched(): Addressing concerns about specialized filesystem accessibility, this method adopts sched_getaffinity(), essentially a syscall, to deduce the number of CPUs. This syscall-based approach aligns with the desire for a more reliable, system-level means to retrieve CPU count information, bypassing potential dependencies on file system structures.

    Despite glibc’s vastness and varied system support, its Linux implementation of sysconf() prioritizes sysfs as the primary resource for CPU count retrieval, supplemented by fallback methods for contingencies or specialized system scenarios.

    musl implementation:

    Developed with a distinct focus on constrained systems, musl libc embodies the quintessential choice for environments with stringent resource limitations. Unveiling musl’s methodology for retrieving CPU count information unveils a strategy tailored to suit such constrained environments.

    In contrast to glibc’s expansive versatility, musl prioritizes efficiency and minimalism, aligning with the requirements of resource-constrained systems. musl’s approach to CPU count retrieval centers around a singular method, reliant on the sched_getaffinity() syscall to infer CPU count.

    This method, employing sched_getaffinity(), emphasizes a syscall-based approach for determining CPU count information. While not leveraging sysfs or other file system structures, musl’s implementation demonstrates a steadfast reliance on system-level calls for this critical system attribute. This approach aligns with musl’s ethos of simplicity and efficiency, avoiding potential dependencies on file system structures and instead relying solely on syscall interactions to obtain CPU count details.

    musl’s singular reliance on sched_getaffinity() for CPU count retrieval underscores its commitment to efficiency and simplicity in constrained system environments, reflecting its status as a libc tailored specifically for resource-limited setups.

    ulibc implementation:

    ulibc, akin to musl, stands as a libc tailored explicitly for resource-constrained systems. Its implementation strategy for CPU count retrieval reflects a minimalistic approach, aligning with the requirements of such constrained environments.

    Despite the expectation of multiple methods to cater to contingencies, ulibc’s decision to rely solely on a sysfs based approach might initially surprise. The implementation involves scanning the sysfs directory /sys/devices/system/cpu, specifically enumerating directory entries featuring the substring ‘cpu[0-9]’. This singular method utilizing sysfs as the source for CPU count determination aligns with ulibc’s ethos of minimalism and efficiency.

    This reliance on sysfs, while potentially limiting if sysfs isn’t mounted, resonates with ulibc’s targeted service provision to highly constrained systems. The decision potentially avoids additional overhead that could arise from using syscall-based methods, as it requires a support structure having a non-negligible footprint, incompatible with resource-limited environments.

    nproc Utility:

    Examining the nproc utility, it’s pertinent to delve into two notable implementations: Coreutils and Busybox. Despite the varying nature of these utilities, the expectation leans toward both implementations relying on support from the underlying libc to provide CPU count information.

    Coreutils Implementation:

    Coreutils, a fundamental suite of Unix utilities including nproc, typically relies on libc support for system-specific information retrieval. The nproc utility in Coreutils is expected to utilize system calls or libc functions to fetch CPU count data. Upon inspecting the nproc utility’s codebase, it becomes evident that the utility itself does not house specific code for CPU count retrieval. Instead, it relies on certain environment variables typically provided by the OpenMP library. In the absence of these variables, nproc falls back on a function named num_processors_ignoring_omp(), which finds its implementation within the gnulib.

    The gnulib implementation might initially appear complex, owing to its handling of the task across diverse platforms, including one for Windows. However, restricting the investigation to Linux unveils an implementation primarily reliant on the sched_getaffinity() syscall. Remarkably, this implementation appears independent of direct dependencies on the libc, offering an alternative method for CPU count retrieval.

    By leaning on sched_getaffinity(), the gnulib implementation for Linux within nproc exemplifies a straightforward syscall-based approach for CPU count determination, suggesting a certain level of autonomy from standard libc functionalities.

    Busybox Implementation:

    Busybox, renowned for its compactness and versatility, reimagines system utilities, often independent of direct dependencies on standard libraries like libc. The implementation of CPU count retrieval within Busybox resonates with this independent ethos, showcasing a self-contained logic mirroring methodologies akin to libc implementations.

    Busybox’s CPU count retrieval method primarily involves scanning the sysfs directory /sys/devices/system/cpu, specifically enumerating directory items containing the substring cpu. However, this method assumes prominence only when a configuration symbol is enabled, signifying Busybox’s adaptability based on configuration choices.

    The surprising element lies in Busybox’s delineation of preferences: designating sysfs-based enumeration as the primary and fallback method, whereas the sched_getaffinity() syscall serves as an alternative choice. This nuanced approach differs from conventional expectations, underscoring Busybox’s nuanced perspective on reliability and system adaptability.

    Despite sharing similarities with libc-based implementations in sysfs enumeration, Busybox’s developers view the syscall-based approach as a secondary yet dependable method. This acknowledgment highlights sched_getaffinity() as an alternative in scenarios permitting multiple methods, but also as the preferred method when only one can be chosen.

    Consideration about Portability:

    Having explored various existing methods for accessing CPU count data, it’s apparent that despite the availability of libc-provided methods, many userspace utilities opt to implement their own functions for this purpose. Reflecting on this, in a new implementation, the recommendation leans toward leveraging the libc-provided method, specifically sysconf(_SC_NPROCESSORS_CONF). This approach ensures compatibility and adherence to standard interfaces across diverse Linux environments.

    However, in specific scenarios where unique constraints exist, such as employing ulibc in an environment without accessible or mountable special filesystems, it may necessitate a custom implementation for CPU count retrieval. In such cases, an alternative suggestion would be to base the implementation on the sched_getaffinity() syscall, given its usability across varied contexts.

    Method description usable memory footprint
    Sysfs file /sys/devices/system/cpu/possible the file gets accessed and it contains the number we need when sysfs is mounted lowest
    sysfs directory /sys/devices/system/cpu the directory is scanned and cpu[0-9]+ subdirectories are searched. Count the items provides the number. when sysfs is mounted low
    procfs file parsing /proc/cpuinfo the file is accessed and the contents parsed. Counting CPU occurence provides the number. when procfs is mounted medium
    sched_getaffinity() the scheduler affinity table is copied to the userspace, items are counted. always possibly high

    sched_getaffinity() sample implementation

    To end this article I want to provide a sched_getaffinity() based sample implementation.

    #define _GNU_SOURCE
    #include <sched.h>
    
    #define MAX_CPUS 2048
    
    int nproc(void){
            unsigned long mask[MAX_CPUS];
            unsigned long m;
            int count = 0;
            int i;
    
            if (sched_getaffinity(0, sizeof(mask), (void*)mask) == 0) {
                    for (i = 0; i < MAX_CPUS; i++) {
                            m = mask[i];
                            while (m) {
                                    if (m & 1) count++;
                                    m >>= 1;
                            }
                    }
            }
            return count;
    }
    

    Sunday, May 7, 2023

    Never Lose a Command Again: How to Centralize Your Bash Command History


    Have you ever found yourself in a situation where you needed to recall a command that you had used in the past, only to find out that it was no longer available in your command history?

    If so, you're not alone. It's a common problem for anyone who uses a command line interface on a regular basis.
    To address this issue, one solution is to log all of your commands in a central server. This allows you to access your command history from any machine that you may have used. In this post, we'll explore a simple way to achieve this using bash and netcat.
    First, let's start with the client-side implementation. Bash provides an environment variable called PROMPT_COMMAND, which is a command that is run every time the prompt is printed on the screen.
    By setting PROMPT_COMMAND to a command that sends the current command to a server using netcat, we can easily log all of our commands. Netcat, also known as "nc", is a versatile networking utility that can be used for a wide range of purposes, including sending and receiving data over TCP or UDP connections.
    There are several different implementations of netcat available, each with its own set of features and options. Some of the most popular netcat implementations include:
    • GNU Netcat - The GNU implementation of netcat, also known as "nc", is the most widely used version of netcat. It includes a wide range of features and options, including support for TCP and UDP, port scanning, and remote shell access.
    • OpenBSD Netcat - OpenBSD's version of netcat, also known as "nc", is designed to be secure and portable. It includes support for IPv6 and encryption using SSL/TLS.
    • BusyBox Netcat - BusyBox is a lightweight Linux distribution that includes a variety of common Unix utilities, including a minimalist version of netcat. BusyBox netcat is designed to be small and fast, and includes support for basic TCP and UDP connections.
    It's worth noting that different versions of netcat may have different options and behavior, so it's important to check the documentation for your specific implementation to ensure that you're using it correctly. In the context of logging command history, we've used the most basic version of netcat without any options, as it provides the core functionality we need without adding unnecessary complexity.
    Here's an example of how to set up PROMPT_COMMAND:

    export PROMPT_COMMAND='echo "$(date +%Y%m%d.%H%M%S) - $(hostname -A) > $(history -w /dev/stdout | tail -n1)"|nc server.example.com 12345'

    This command sends the most recent command from the command history to the server server.example.com on port 12345 using netcat. Note that we're using the history command to retrieve the most recent command.
    Now let's move on to the server-side implementation. Initially, we had planned to use netcat to receive the data from the client, but we found that we needed some uncommon features that netcat does not provide. As a result, we decided to implement the server in a single Golang application.

    In conclusion, logging your command history to a central server can be a great way to keep track of your commands and make them easily accessible from any machine. By using bash and netcat, we've provided a simple and efficient way to implement this solution. However, depending on your requirements, you may need to use a more complex solution like the Golang application that we ended up implementing.